foundation-model ·
Qwen3.6-35B-A3B-FP8
任务类型:image-text-to-text
# Qwen3.6-35B-A3B-FP8 [](https://chat.qwen.ai)
> [!Note]
> This repository contains FP8-quantized model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
>
> The quantization method is fine-grained fp8 quantization with block size of 128, and its performance metrics are nearly identical to those of the original model.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
## Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- **Agentic Coding:** the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- **Thinking Preservation:** we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post [Qwen3.6-35B-A3B](https://qwen.ai/blog?id=qwen3.6-35b-a3b).
## Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 35B in total and 3B activated
- Hidden Dimension: 2048
- Token Embedding: 248320 (Padded)
- Number of Layers: 40
- Hidden Layout: 10 × (3 × (Gated DeltaNet → MoE) → 1 × (Gated Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 32 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 16 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Mixture Of Experts
- Number of Experts: 256
- Number of Activated Experts: 8 Routed + 1 Shared
- Expert Intermediate Dimension: 512
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
## Benchmark Results
### Language
| Qwen3.5-27B | Gemma4-31B | Qwen3.5-35BA3B | Gemma4-26BA4B | Qwen3.6-35BA3B | |
|---|---|---|---|---|---|
| Coding Agent | |||||
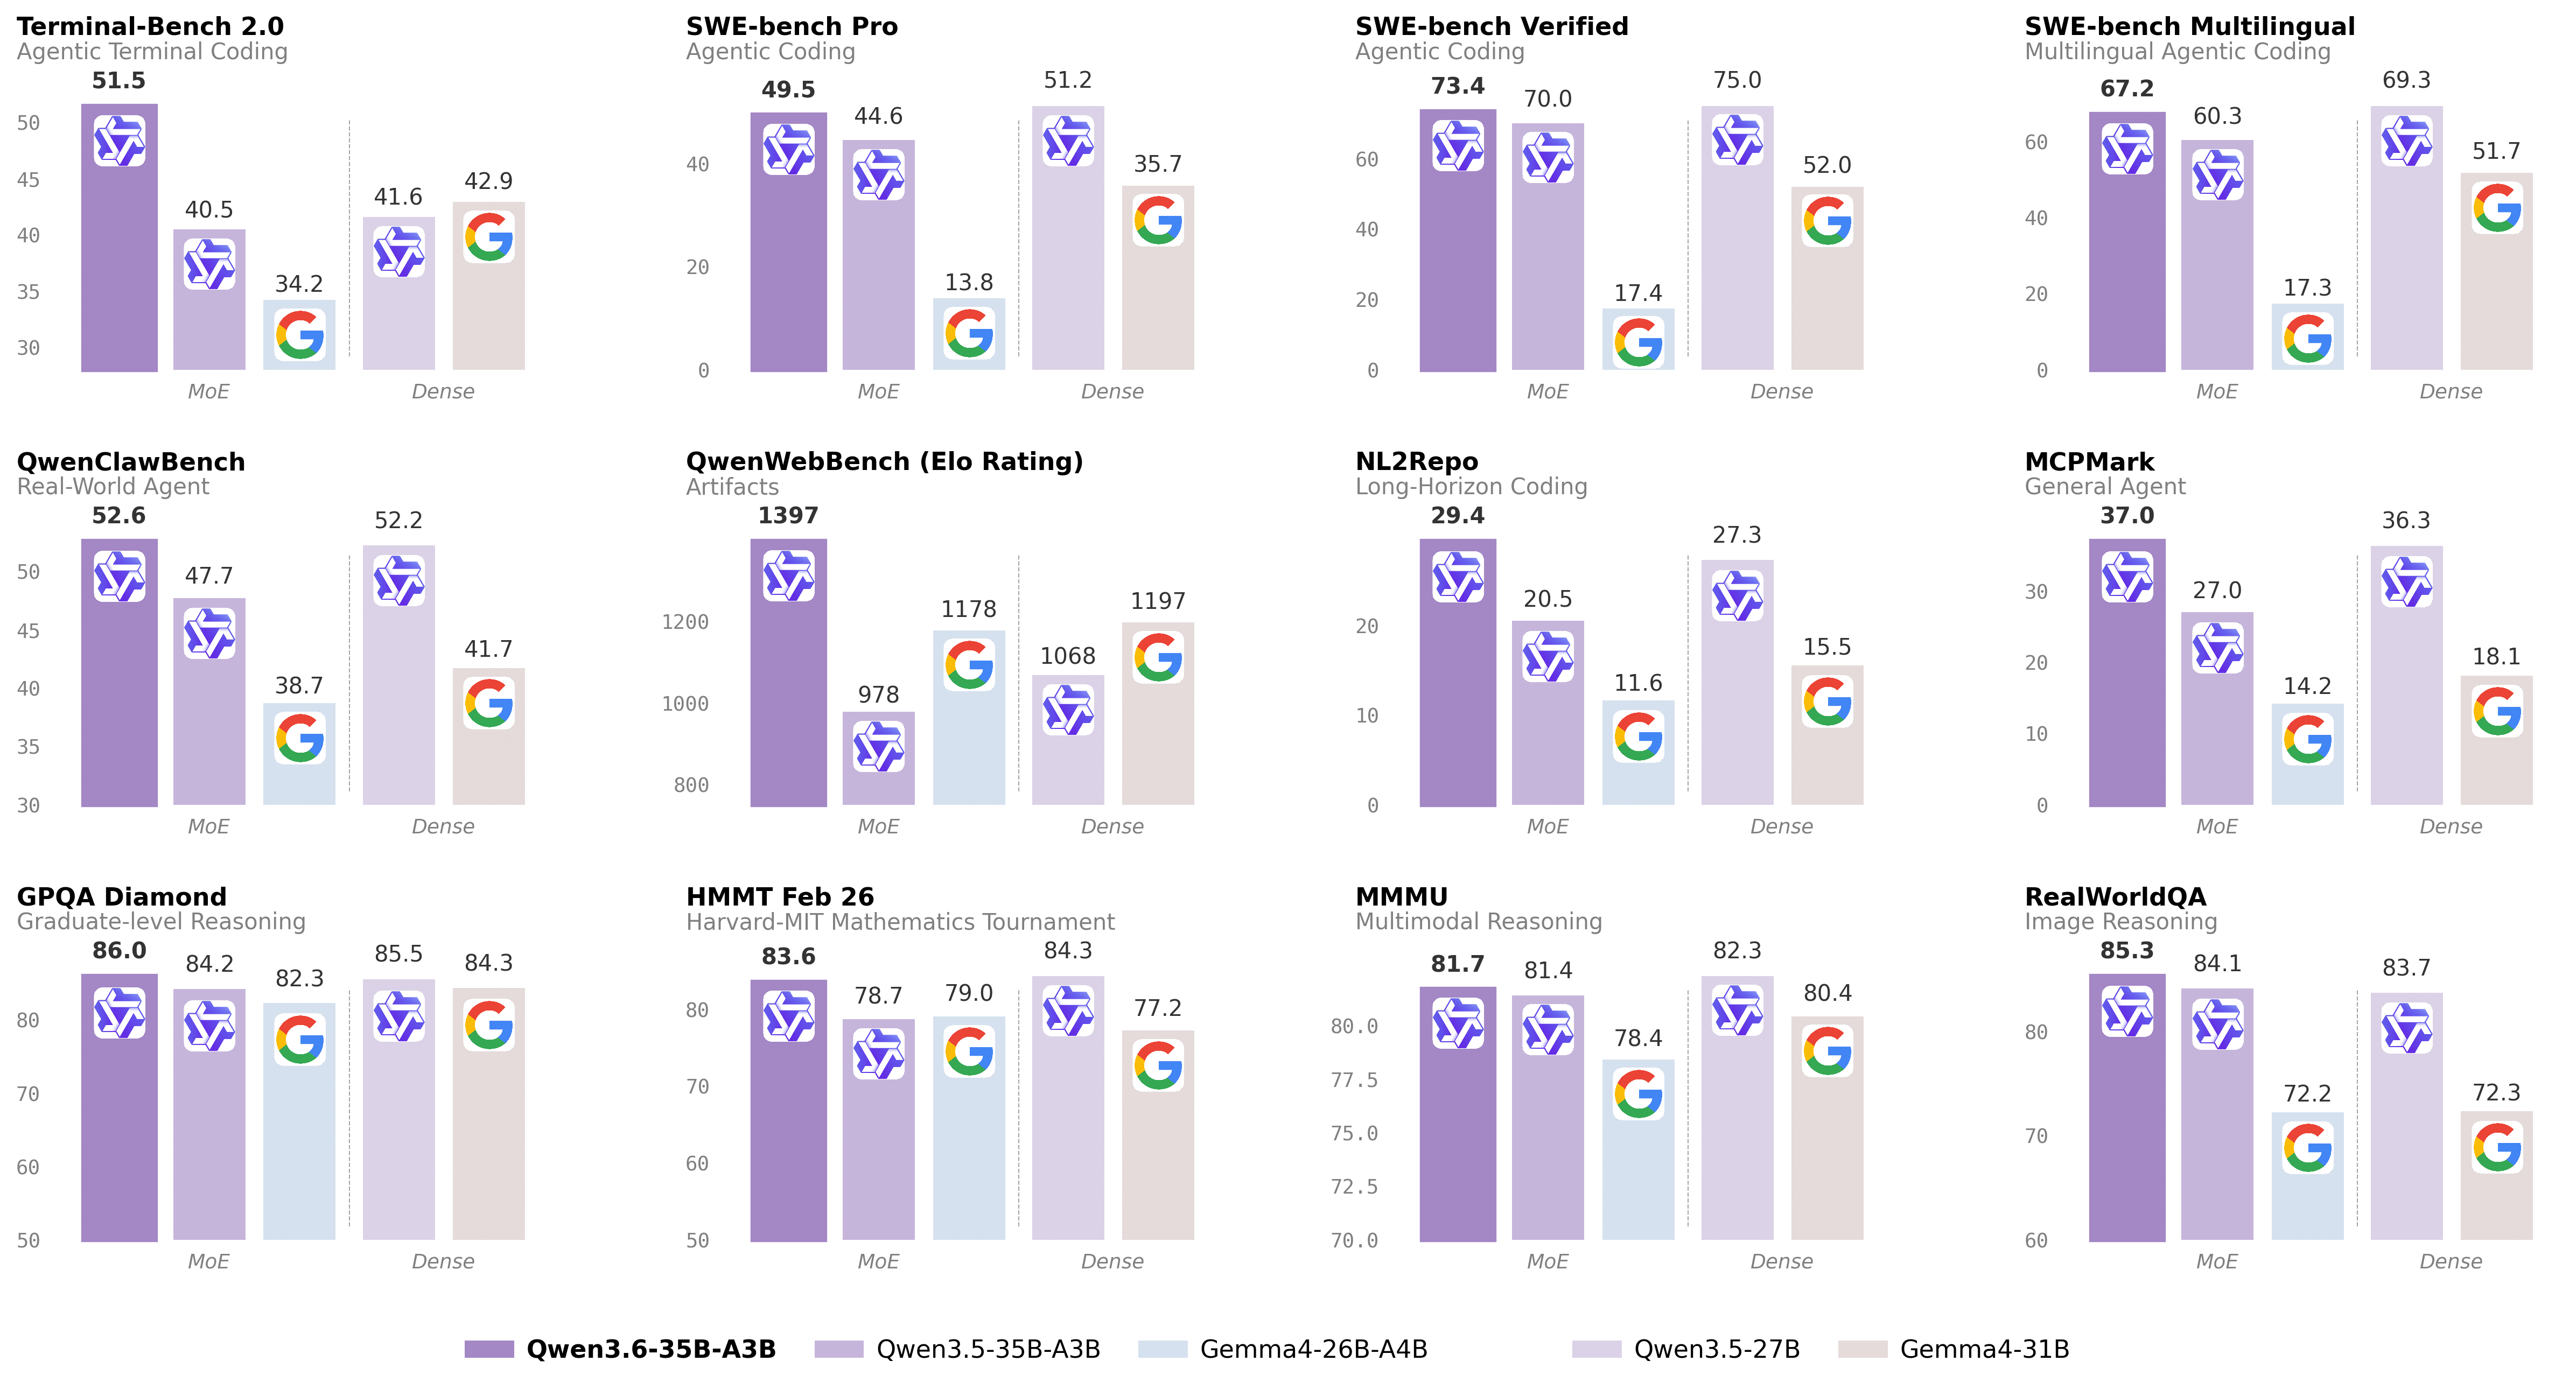
| SWE-bench Verified | 75.0 | 52.0 | 70.0 | 17.4 | 73.4 |
| SWE-bench Multilingual | 69.3 | 51.7 | 60.3 | 17.3 | 67.2 |
| SWE-bench Pro | 51.2 | 35.7 | 44.6 | 13.8 | 49.5 |
| Terminal-Bench 2.0 | 41.6 | 42.9 | 40.5 | 34.2 | 51.5 |
| Claw-Eval Avg | 64.3 | 48.5 | 65.4 | 58.8 | 68.7 |
| Claw-Eval Pass^3 | 46.2 | 25.0 | 51.0 | 28.0 | 50.0 |
| SkillsBench Avg5 | 27.2 | 23.6 | 4.4 | 12.3 | 28.7 |
| QwenClawBench | 52.2 | 41.7 | 47.7 | 38.7 | 52.6 |
| NL2Repo | 27.3 | 15.5 | 20.5 | 11.6 | 29.4 |
| QwenWebBench | 1068 | 1197 | 978 | 1178 | 1397 |
| General Agent | |||||
| TAU3-Bench | 68.4 | 67.5 | 68.9 | 59.0 | 67.2 |
| VITA-Bench | 41.8 | 43.0 | 29.1 | 36.9 | 35.6 |
| DeepPlanning | 22.6 | 24.0 | 22.8 | 16.2 | 25.9 |
| Tool Decathlon | 31.5 | 21.2 | 28.7 | 12.0 | 26.9 |
| MCPMark | 36.3 | 18.1 | 27.0 | 14.2 | 37.0 |
| MCP-Atlas | 68.4 | 57.2 | 62.4 | 50.0 | 62.8 |
| WideSearch | 66.4 | 35.2 | 59.1 | 38.3 | 60.1 |
| Knowledge | |||||
| MMLU-Pro | 86.1 | 85.2 | 85.3 | 82.6 | 85.2 |
| MMLU-Redux | 93.2 | 93.7 | 93.3 | 92.7 | 93.3 |
| SuperGPQA | 65.6 | 65.7 | 63.4 | 61.4 | 64.7 |
| C-Eval | 90.5 | 82.6 | 90.2 | 82.5 | 90.0 |
| STEM & Reasoning | |||||
| GPQA | 85.5 | 84.3 | 84.2 | 82.3 | 86.0 |
| HLE | 24.3 | 19.5 | 22.4 | 8.7 | 21.4 |
| LiveCodeBench v6 | 80.7 | 80.0 | 74.6 |
原始来源:https://huggingface.co/Qwen/Qwen3.6-35B-A3B-FP8/blob/main/README.md